Data Engineer
You’ll be the boss. Sifflet gives you the capabilities and oversight to manage your data stack like never before, faster than you ever thought possible.

Troubleshoot and Debug
Sifflet makes troubleshooting and debugging faster, more efficient and more effective thanks to pipeline failure or data anomaly alerts and rich contextual information.
Pipeline Performance Optimization
Pipelines power your data stack. Sifflet helps you monitor pipeline performance and get insight into bottlenecks and inefficient transformations.

Quality Assurance
Uplevel your data quality thanks to automated quality checks and validations and custom rules to ensure data integrity.
More Productive. More Powerful.
Sifflet augments your productivity by giving you end-to-end visibility into your architecture, assets, and pipelines. AI-powered monitoring sends you the right alerts, at the right time, so you can triage efficiently and effectively. And advanced lineage capabilities enable you to get to resolution faster.
Built for Business.
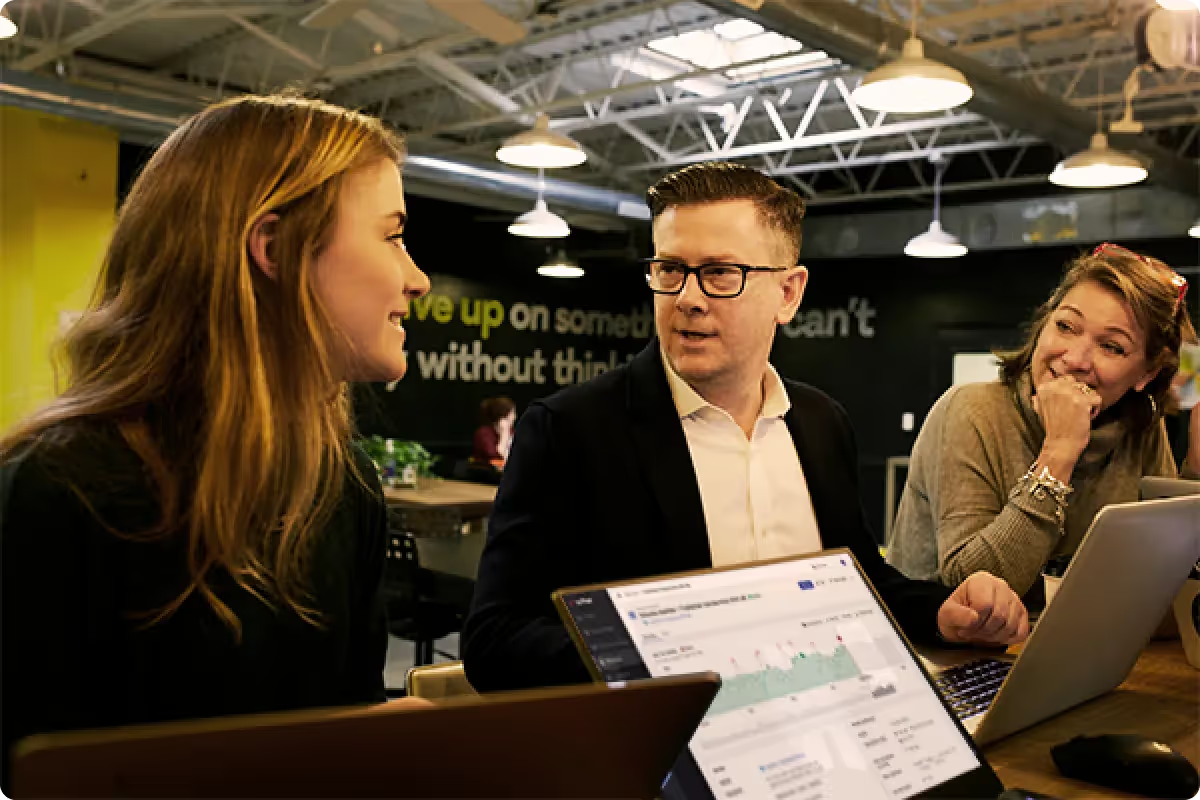
Sifflet helps you collaborate better with users on the business end. Give your data consumers self-serve tools, such as smart monitoring setup that leverages large language models and embed monitoring alerts into their data products.
See Value From Day One.
Sifflet connects to hundreds of tools already in your stack and offers out of the box monitors and tooling so you can start seeing value from day one.

Sifflet’s AI Helps Us Focus on What Moves the Business
What impressed us most about Sifflet’s AI-native approach is how seamlessly it adapts to our data landscape — without needing constant tuning. The system learns patterns across our workflows and flags what matters, not just what’s noisy. It’s made our team faster and more focused, especially as we scale analytics across the business.
"Enabler of Cross Platform Data Storytelling"

"Sifflet has been a game-changer for our organization, providing full visibility of data lineage across multiple repositories and platforms. The ability to connect to various data sources ensures observability regardless of the platform, and the clean, intuitive UI makes setup effortless, even when uploading dbt manifest files via the API. Their documentation is concise and easy to follow, and their team's communication has been outstanding—quickly addressing issues, keeping us informed, and incorporating feedback. "
"Building Harmony Between Data and Business With Sifflet"

"Sifflet serves as our key enabler in fostering a harmonious relationship with business teams. By proactively identifying and addressing potential issues before they escalate, we can shift the focus of our interactions from troubleshooting to driving meaningful value. This approach not only enhances collaboration but also ensures that our efforts are aligned with creating impactful outcomes for the organization."
" Sifflet empowers our teams through Centralized Data Visibility"

"Having the visibility of our DBT transformations combined with full end-to-end data lineage in one central place in Sifflet is so powerful for giving our data teams confidence in our data, helping to diagnose data quality issues and unlocking an effective data mesh for us at BBC Studios"
"Sifflet allows us to find and trust our data"

"Sifflet has transformed our data observability management at Carrefour Links. Thanks to Sifflet's proactive monitoring, we can identify and resolve potential issues before they impact our operations. Additionally, the simplified access to data enables our teams to collaborate more effectively."
"A core component of our data strategy and transformation"

"Using Sifflet has helped us move much more quickly because we no longer experience the pain of constantly going back and fixing issues two, three, or four times."


Frequently asked questions